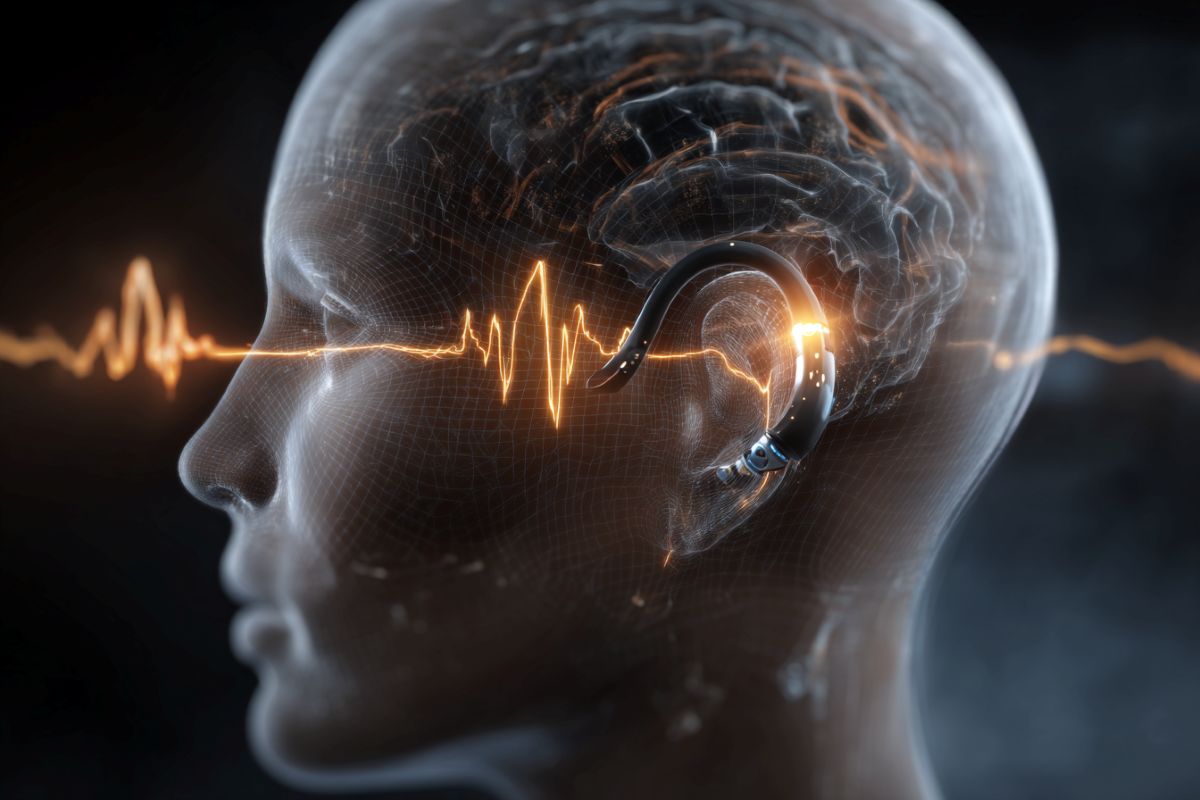
Abstract: Researchers offered the primary direct proof that brain-controlled expertise can assist listeners isolate a single voice in a crowded setting. The examine demonstrates a system that acts as a “neural extension,” using real-time mind indicators to determine which speaker an individual is specializing in and robotically amplifying that particular voice.
This breakthrough addresses the “cocktail get together impact”, a serious limitation of standard listening to aids, which frequently battle to tell apart between overlapping conversations in noisy settings.
Key Analysis Findings
- The Mind-First Strategy: Not like conventional listening to aids that indiscriminately amplify all incoming sounds, this method leverages the mind’s pure capacity to filter complicated environments.
- Actual-Time Identification: Utilizing machine-learning algorithms, the system displays the timing of mind wave “peaks and valleys” to match them with the particular patterns of a dialog.
- Direct Human Proof: The examine concerned epilepsy sufferers with pre-implanted electrodes; the system appropriately recognized their focus and adjusted volumes immediately, considerably enhancing speech intelligibility and lowering “listening effort”.
- Dynamic Flexibility: The expertise functioned efficiently each when topics have been guided to a speaker and once they selected a dialog freely, mirroring real-world social dynamics.
- Sensible Software: This analysis marks the transition of brain-controlled listening to from theoretical science to a purposeful prototype that gives fast, real-time advantages.
Supply: Columbia College
Scientists at Columbia College’s Zuckerman Institute have the primary direct proof from human research that brain-controlled listening to expertise can assist folks single out a voice in a crowd.
These early findings counsel that researchers could someday develop a listening to augmentation system that may, amongst different feats, overcome the issues that standard listening to aids have with noisy environment.

Their analysis was revealed on-line at this time in Nature Neuroscience.
“We now have developed a system that acts as a neural extension of the consumer, leveraging the mind’s pure capacity to filter by way of all of the sounds in a fancy setting to dynamically isolate the particular dialog they want to hear,” stated senior creator Nima Mesgarani, PhD, a principal investigator at Columbia’s Zuckerman Institute and an affiliate professor {of electrical} engineering at Columbia’s Fu Basis Faculty of Engineering and Utilized Science.
“This science empowers us to suppose past conventional listening to aids, which merely amplify sound, towards a future the place expertise can restore the subtle, selective listening to of the human mind,” Dr. Mesgarani added.
Within the new examine, Columbia researchers teamed up with surgeons and their epilepsy sufferers who have been present process mind surgical procedure to higher pinpoint the sources of their seizures. The hospital sufferers, who volunteered to be a part of this examine, already had electrodes implanted of their brains.
Dr. Mesgarani’s system used the electrodes to measure the mind exercise of the sufferers as they targeted on one in every of two overlapping conversations performed concurrently. The system then robotically detected which dialog a affected person was taking note of and adjusted the amount in actual time, turning up that dialog whereas quieting the opposite.
For one volunteer, the expertise of controlling the system together with her mind was actually unbelievable. She accused the researchers of secretly adjusting the volumes. Others informed tales about family and friends with listening to impairments who may gain advantage from such a expertise. One particular person stated: “It looks like science fiction.”
Fashionable listening to aids excel at amplifying speech whereas suppressing sure sorts of background noise, comparable to visitors. However they can not separate and improve explicit voices of curiosity; they enhance each voice coming into the microphone indiscriminately. This makes it tough for folks to focus on a particular talker amidst a jumble of voices.
A promising answer to this drawback is a listening to system that might mimic the best way wherein the human mind can usually determine and concentrate on only one speaker in a crowd, a phenomenon typically referred to as the cocktail get together impact.
In 2012, Dr. Mesgarani and his colleagues found methods to determine which units of mind indicators are linked with particular conversations amidst crowds of audio system. For instance, the timing of peaks and valleys of mind waves can match up with the sounds and silences inside a dialog. In addition they discovered {that a} distinct sample of mind exercise can reveal which dialog an individual was specializing in and which they have been filtering out.
These discoveries might someday result in real-world listening to help and augmentation gadgets that may monitor mind waves to detect and amplify the dialog an individual is most interested by.
Over the course of a whole bunch of extra research prior to now decade or so, Dr. Mesgarani and others have overcome a bunch of challenges making an attempt to make this dream a actuality, comparable to growing pc algorithms to robotically separate out the voices of a number of audio system in a gaggle, after which examine the voice of every speaker to the mind waves of a listener.
“The central unanswered query was whether or not brain-controlled listening to expertise might transfer past incremental advances, in direction of a prototype that might assist somebody hear higher in actual time,” stated Vishal Choudhari, the paper’s first creator, who obtained his PhD in electrical engineering whereas in Dr. Mesgarani’s lab and who led the event and analysis of the system.
“For the primary time, we’ve proven that such a system that reads mind indicators to selectively improve conversations can present a transparent real-time profit. This strikes brain-controlled listening to from idea towards sensible software.”
The researchers partnered with physicians and sufferers who volunteered to be a part of the examine on the Hofstra Northwell Faculty of Drugs; the Feinstein Institutes for Medical Analysis, New York College Faculty of Drugs; and the College of California San Francisco’s Division of Neurological Surgical procedure.
The scientists developed real-time machine-learning algorithms that might look at the brainwaves and determine which dialog the sufferers have been taking note of. As soon as deployed, their system might quickly deduce which dialog every listener was taking note of and make it simpler for them to listen to it.
This occurred each when the researchers guided the topics towards a specific dialog, and when the topics selected freely, as can be vital in a real-world dialog.
“For this to work in actual time, the system needs to be very quick, correct and steady for the expertise to really feel nice for the listener,” Dr. Mesgarani stated.
The scientists discovered their new system appropriately recognized which dialog the volunteers paid consideration to. This dramatically improved the intelligibility of the speech the volunteers targeted on, lowered listening effort, and was persistently most well-liked by the volunteers when in comparison with conversations the system didn’t present help with.
One volunteer recalled her uncle, who had listening to issues. “Are you able to think about if this expertise existed in a world [where] … he might entry it? He would possibly really reside a way more peaceable… life.”
Based on the World Well being Group, greater than 430 million folks worldwide reside with disabling listening to loss, lots of whom battle most in noisy social environments. Untreated listening to loss is a number one modifiable danger issue for dementia, in addition to a main contributor to despair and social isolation.
Scientists say this analysis lays the groundwork for future wearable techniques that might someday combine mind sensing with superior audio processing. This could help folks with listening to loss and probably increase listening to and cut back fatigue from listening for anybody in on a regular basis difficult environments comparable to eating places, school rooms, busy workplaces and household gatherings.
The scientists be aware that an excessive amount of work is required earlier than this expertise is accessible in a wearable kind that may work in a minimally invasive manner in additional difficult real-world eventualities. As an example, they might someday prefer to see how properly their system can carry out in real-world listening situations that are extra complicated, Dr. Mesgarani stated.
“The outcomes mark an necessary step towards a brand new era of brain-controlled listening to applied sciences that align with the listener’s intent, probably reworking how folks navigate noisy, multi-talker environments,” Dr. Choudhari added.
The complete record of authors consists of Vishal Choudhari, Maximilian Nentwich, Sarah Johnson, Jose L. Herrero, Stephan Bickel, Ashesh D. Mehta, Daniel Friedman, Adeen Flinker, Edward F. Chang, and Nima Mesgarani.
Funding: This work was funded by grants from the Marie-Josee and Henry R. Kravis Basis and the Nationwide Institute of Well being’s Nationwide Institute on Deafness and Different Communication Problems.
Key Questions Answered:
A: Whereas this examine used surgical electrodes for precision, the last word purpose is to develop wearable, minimally invasive techniques that combine mind sensing with audio processing for on a regular basis use.
A: Each voice has a novel “rhythm” of sound and silence. Your mind exercise syncs up with these particular rhythms whenever you focus. The system’s algorithms examine the mind waves of the listener to the separate voice streams it detects and “matches” them.
A: Disabling listening to loss impacts over 430 million folks and is a main danger issue for dementia, despair, and social isolation. Expertise that makes social environments “peaceable” once more might considerably cut back the cognitive fatigue and isolation related to listening to impairment.
Editorial Notes:
- This text was edited by a Neuroscience Information editor.
- Journal paper reviewed in full.
- Further context added by our employees.
About this auditory neuroscience and neurotech analysis information
Writer: Nima Mesgarani, PhD
Supply: Columbia College
Contact: Nima Mesgarani, PhD – Columbia College
Picture: The picture is credited to Neuroscience Information
Authentic Analysis: Open entry.
“Actual-time brain-controlled selective listening to enhances speech notion in multi-talker environments” by Vishal Choudhari, Maximilian Nentwich, Sarah Johnson, Jose L. Herrero, Stephan Bickel, Ashesh D. Mehta, Daniel Friedman, Adeen Flinker, Edward F. Chang & Nima Mesgarani. Nature Neuroscience
DOI:10.1038/s41593-026-02281-5
Summary
Actual-time brain-controlled selective listening to enhances speech notion in multi-talker environments
Understanding speech in noisy environments is tough for many individuals, and present listening to aids usually fail as a result of they amplify all sounds somewhat than the talker of curiosity.
Auditory consideration decoding (AAD) provides a possible answer through the use of the listener’s mind indicators to determine and improve the attended speaker, however it has been unclear whether or not this could present real-time perceptual advantages.
Right here we used high-resolution intracranial electroencephalography in sufferers present process neurosurgical procedures to implement a closed-loop system that achieves the decoding constancy essential to dynamically amplify the attended talker.
Throughout a number of experiments, the system improved speech intelligibility, lowered listening effort and was persistently most well-liked by topics. It additionally tracked each instructed and self-initiated consideration shifts.
By offering direct proof {that a} real-time, brain-controlled listening to system can improve notion, this work establishes a key efficiency benchmark for future auditory mind–pc interfaces and advances AAD from a theoretical idea to a validated answer for personalised assistive listening to.